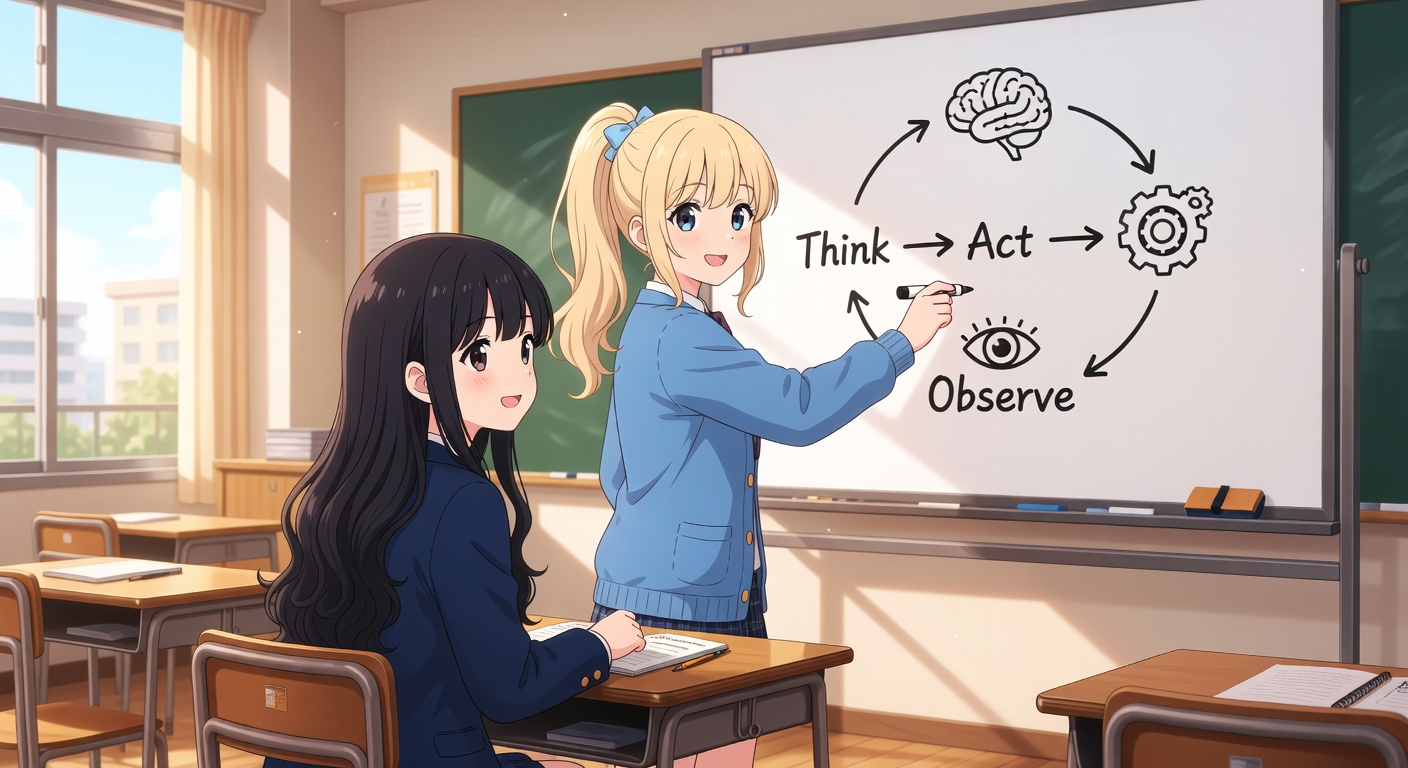
🔄 The Secret Behind AI That Works on Its Own
So far we’ve been learning the core components of AI agents one by one. In Episode 2 we covered the brain (LLM), in Episode 3 the hands (Tool Use), and in Episode 4 the memory (context and memory).
But do those components alone make an agent? Nope! What you need is a structure that connects all three and repeats on its own. That’s exactly what we’re learning today — the Agent Loop.
Hold on, what even is a “loop”? Can’t you just ask the AI and it figures it out?
Great question! Ask once, get one answer — that’s just a “chatbot.” An agent keeps thinking, acting, and checking results on its own until it reaches the goal. That repeating structure is the loop!
Let me give you an example. When you tell Claude Code “fix this bug,” here’s what actually happens:
- Read the code and analyze the problem (Think)
- Modify the file (Act)
- Run tests and check the results (Observe)
- Tests fail? → Back to step 1!
This process performs an average of 21.2 tool calls without any human intervention, according to the official Anthropic documentation. It’s a completely different dimension from a chatbot that’s done after one exchange!
The core operational structure in which an AI agent repeats “Think → Act → Observe” until it achieves its goal. Think of it like a chef who keeps cycling through “check the recipe → cook → taste” until the dish is right!
🧠 Think → Act → Observe — The Three-Step Cycle
The agent loop is made up of three steps.

1. Think — The LLM analyzes the current situation and decides what to do next. Something like: “There’s a missing null check in this code. I need to fix it.”
2. Act — Based on that decision, it calls a tool. Reading a file, editing code, running a search — this is where the Tool Use we covered in Episode 3 really shines!
3. Observe — It checks the result of the action. It looks at what the tool returned and judges: “Did it succeed? Is there more to do?”
So does this cycle just keep spinning forever?
No! The loop ends when the goal is reached. More precisely, when the LLM decides “I don’t need to call any more tools,” it just returns a final text response and the loop terminates.
📜 The ReAct Pattern — Academic Origins
This “think and act” pattern has an official name: ReAct.
An AI agent pattern that alternates between reasoning and acting. It was proposed in a paper published by Princeton University and Google in 2022.
In October 2022, a research team from Princeton University and Google published a paper titled “ReAct: Synergizing Reasoning and Acting in Language Models.” Accepted at ICLR 2023, it became a foundational work in AI agent research.
The core idea behind ReAct is simple:
- Reasoning (Thought) forms action plans and handles edge cases
- Acting (Action) interacts with external information sources
- Alternating between the two is far more powerful than either alone
In real experiments, ReAct significantly reduced hallucinations and error propagation on Wikipedia search tasks (HotpotQA), and achieved a 34% higher success rate than prior methods in game environments (ALFWorld).
So Claude Code uses the ReAct pattern too?
Exactly! If you look at Claude Code’s official documentation, it describes a blended version of three steps — gather context → take action → verify results. The names are a bit different, but the essence is the same as ReAct!
⚙️ Claude’s Agent Loop — How It Actually Works
Here’s how the agent loop operates in the Claude Agent SDK:
- Receive prompt — user request + system prompt + tool definitions + conversation history
- Evaluate / respond — Claude returns text, tool calls, or both
- Execute tools — the SDK runs the tools and collects the results
- Feedback — the results are passed back to Claude
- Repeat — steps 2–4 repeat; if there are no tool calls, terminate
In code, it’s surprisingly simple. The heart of it is a while loop:
# Core structure of the Claude Agent Loop (pseudocode)
while True:
    # 1. Send the current state to the LLM
    response = claude.send(messages)

    # 2. Check whether there are any tool calls
    if not response.has_tool_calls():
        # No tool calls → final answer!
        print(response.text)
        break

    # 3. Execute tools & collect results
    for tool_call in response.tool_calls:
        result = execute_tool(
            tool_call.name,
            tool_call.arguments
        )
        # 4. Append the result to the conversation
        messages.append(
            tool_result(result)
        )
This simple structure is the source of all of Claude Code’s magic. Safety mechanisms like max_turns and max_budget_usd make sure it doesn’t run forever.
max_turns (maximum iteration count), max_budget_usd (cost ceiling), and the effort level (low/medium/high/max).
💻 Let’s Build It Ourselves! — A Mini Agent Loop
Let’s build our own agent loop! Here’s a simple “weather lookup agent.”
import anthropic, json

client = anthropic.Anthropic()
MAX_TURNS = 10  # Prevent infinite loops!

# Tool definition
tools = [{
    "name": "get_weather",
    "description": "Get current weather for a city",
    "input_schema": {
        "type": "object",
        "properties": {
            "city": {
                "type": "string",
                "description": "City name"
            }
        },
        "required": ["city"]
    }
}]

# Tool execution function
def run_tool(name, args):
    if name == "get_weather":
        city = args["city"]
        return f"{city}: Sunny, 22°C"
    return "Unknown tool"

# 🔄 Agent loop!
messages = [{"role": "user",
  "content": "Compare the weather in Seoul and Tokyo"}]

for turn in range(MAX_TURNS):
    resp = client.messages.create(
        model="claude-sonnet-4-20250514",
        max_tokens=1024,
        tools=tools,
        messages=messages
    )

    # Only text returned → end the loop
    if resp.stop_reason == "end_turn":
        for block in resp.content:
            if hasattr(block, "text"):
                print(block.text)
        break

    # Handle tool calls
    messages.append(
        {"role": "assistant",
         "content": resp.content})

    for block in resp.content:
        if block.type == "tool_use":
            result = run_tool(
                block.name,
                block.input
            )
            messages.append({
                "role": "user",
                "content": [{
                    "type": "tool_result",
                    "tool_use_id": block.id,
                    "content": result
                }]
            })
            print(f"[Turn {turn+1}]"
                  f" {block.name}"
                  f"({block.input})"
                  f" → {result}")
else:
print("⚠️ Maximum turn count exceeded!")Let me break down the key points of this code!
for turn in range(MAX_TURNS)— safely caps the maximum number of iterations- If the LLM calls a tool → execute it and pass the result back
- If the LLM returns only text → final answer, loop ends!
When you say “Compare the weather in Seoul and Tokyo,” the agent calls get_weather("Seoul") → get_weather("Tokyo") in sequence, then compares the results to produce a final answer. Think → Act → Observe happens automatically!
The full code is available in the GitHub repository.
⚔️ ReAct vs Plan-and-Execute
There are two major strategies for structuring an agent loop.

ReAct (Reactive) — Think and act at every step. Flexible, but can miss the bigger picture.
Plan-and-Execute (Strategic) — Form a complete plan first, then execute it in order. More accurate, but spends more tokens in the planning phase.
| Criteria | ReAct | Plan-and-Execute |
|---|---|---|
| Approach | Think → act at each step | Plan first → execute sequentially |
| Token usage | 2,000–3,000 | 3,000–4,500 |
| Accuracy | 85% | 92% |
| API calls | 3–5 | 5–8 |
| Best for | Simple reactive tasks | Complex multi-step tasks |
In practice, do you just pick one or the other?
Not at all! In practice, hybrid approaches are common. The overall strategy uses Plan-and-Execute, while each individual step runs as ReAct. Claude Code itself follows this kind of hybrid approach!
⚠️ When the Agent Loop Goes Wrong
The agent loop is powerful, but it can fail. According to 2025 research, the failure rate of multi-agent systems ranges from 41% to 86.7% (arXiv:2503.13657).
Let’s look at the most common failure modes:
| Failure Mode | Description | Example |
|---|---|---|
| 🔄 Infinite Loop | Repeats the same action | Outputs the same answer 58 times in a row |
| 🔁 Recursive Failure | Retries a failing approach | Attempts a broken method 100 times |
| 💬 Conversation Loop | Doesn’t know when to stop | Agents endlessly requesting confirmation from each other |
| ✅ Premature Completion | Declares done when it isn’t | “All done!” (but actually not) |

So what happens if an agent gets stuck in an infinite loop? Do we get hit with a massive electricity bill?
That’s exactly why safety guards like max_turns exist! Think of it like a ramen timer~
…Claudie, you’ve forgotten to set the ramen timer before and ended up with mushy noodles, haven’t you?
That was… intentional soft noodles! 😤
To prevent failures, these safety guards are essential:
- Iteration limit — set a hard cap with
max_turns - Cost limit — set a spending ceiling with
max_budget_usd - Progress tracking — log the progress state at every turn
- Result verification — not just unit tests, but end-to-end validation
💰 The Hidden Cost — Token Consumption
The agent loop has a hidden cost. Every turn accumulates system prompt + tool definitions + full conversation history + tool inputs and outputs.
According to OpenReview research, even for the same coding task, token consumption can vary by a factor of 10x depending on the agent — and predicting costs ahead of time is nearly impossible (correlation coefficient r < 0.15).
That’s why the Claude Agent SDK includes these optimizations:
- Auto-compaction — summarizes earlier content when the context gets too long
- Prompt caching — caches repeated system prompts
- Sub-agents — splits independent tasks into separate agents to prevent context explosion
◀ Previous: Episode 4 — AI That Remembers: Context and Memory
▶ Next: Episode 6 — Giving Your Agent a Personality: System Prompt Design (coming soon)

📝 Key Takeaways
- The Agent Loop is a structure that repeats “Think → Act → Observe.” This is the core distinction between a chatbot and an agent.
- The ReAct pattern alternates between Reasoning and Acting — proposed in a 2022 paper from Princeton + Google.
- The heart of Claude Code is a single while loop — keep going if there are tool calls, stop if there aren’t!
- Agent loops carry risks like infinite loops and recursive failures, making safety guards like
max_turnsessential. - Token costs accumulate every turn, so auto-compaction and sub-agents are key optimizations.
- In the next episode, we’ll learn about system prompt design — giving your agent loop a “personality”!
📚 References
- ReAct: Synergizing Reasoning and Acting in Language Models (Yao et al., 2022)
- Anthropic — How Claude Code Works
- Claude Agent SDK — How the Agent Loop Works
- Hugging Face — Agents Course: Thought-Action-Observation
- IBM — What is a ReAct Agent?
- Why Do Multi-Agent LLM Systems Fail? (2025)
- ReAct vs Plan-and-Execute: A Practical Comparison
- Anthropic — Effective Harnesses for Long-Running Agents
- How Do Coding Agents Spend Your Money? (OpenReview, 2025)
- Google Research — ReAct Blog Post
- Claudie’s Agentic AI Classroom Episode 2 — What Is an LLM?
- Claudie’s Agentic AI Classroom Episode 3 — The World of Tool Use
- Claudie’s Agentic AI Classroom Episode 4 — Context and Memory